VMware Cloud on AWS – TMCHAM – Part 16 – Remove External Datastores

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to do a (really) short post on removing external datastores on the VMware-managed VMware Cloud on AWS platform. It might seem like a simple thing, but it can be confusing for customers who haven’t done it before.


The Problem

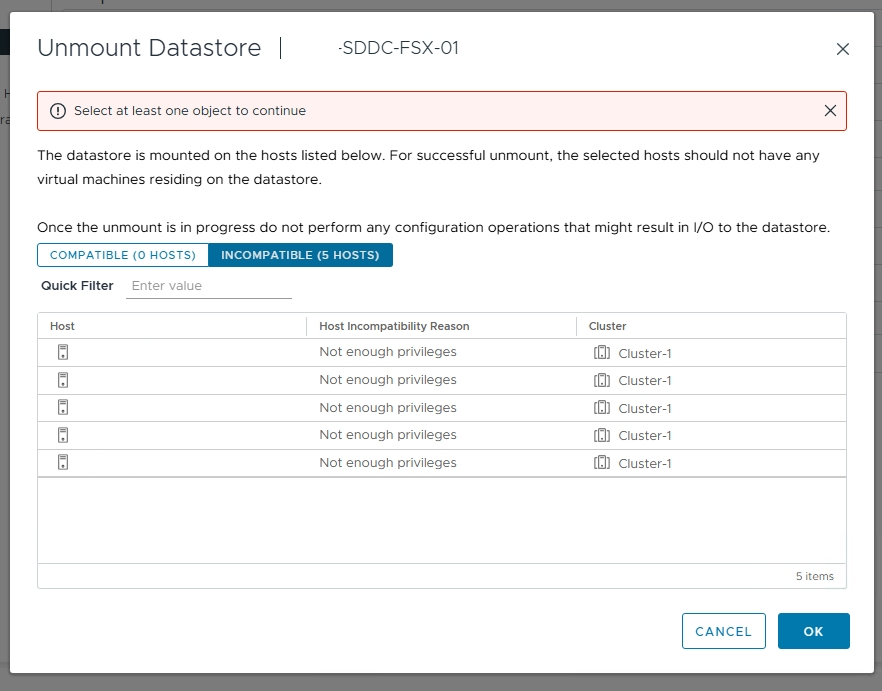
If you’ve used an external datastore (either FSx for NetApp ONTAP or the artist formerly known as VMware Cloud Flex Storage) with your SDDC, you’ll know that management of the connection of the datastores to your SDDC is done via the Cloud Console, and not via vCenter. There might come a time when you want to remove that storage, either because you’ve bought more nodes and want to use vSAN, or you’re possibly shrinking your footprint. Whatever the reason, if you do try to remove the datastore via vCenter (assuming you’ve removed your workloads from the datastore), you’ll get an error about insufficient privileges. At first it might seem like it’s because you have VMs still present on the datastore (and if this is the case, contact Global Support to help you if you can’t find them). It’s more likely, however, that you’re not in the right place to do this activity.


The Solution

The solution is simple. In the VMware Cloud Console, go to the Storage tab of the SDDC you want to remove the datastore from, and click on Detach Datastore. And that’s it. It won’t work if you’ve got workloads running there, so make sure you’ve cleaned everything up / moved it somewhere else before you attempt this one.

VMware Cloud on AWS – What’s New – January 2026

I posted last month about what’s new in VMware Cloud on AWS, particularly as it related to the host usage API and changes to the VMC Sizer tool. It’s a new calendar year, but the team hasn’t stopped, delivering some new updates via a soon to be rolled out VMware Cloud on AWS software bundle. More detail can be found in the VMware Cloud on AWS Release Notes located here, and there’s a great blog post from the team here.


What’s New?

The default version for all new SDDC deployments is now 1.26, and it will be rolled out across the fleet in the next little while. A key component of this release is vSphere 8.0 Update 3. This a long-term support release of vSphere, and delivers improved performance and reliability. Notable, also, is the NSX version – in this update it goes to 4.2.3.1. I’ve linked to it before, but check out the timeless classic “Correlating VMware Cloud on AWS SDDC Versions With Their vSphere Components” for more information. So, an update is great, but what do you really get? Let’s dig in.

Support for vSAN Express Storage Architecture

This is the big one – support for vSAN Express Storage Architecture (ESA) is now generally available for VMware Cloud on AWS. Note that “vSAN ESA is supported only for i4i.metal host types on newly deployed single availability zone SDDCs and for new secondary i4i.metal clusters on existing SDDCs that have been upgraded to 1.26”. So, no brownfield support, but there’s still scope to do some pretty cool stuff.

New vSAN ESA features include:

  • Native snapshots for faster backups;
  • A storage pool architecture that reduces fault domains and improves data availability; and
  • For smaller customers, supports for a RAID-5 storage policy starting from 3 hosts gives customers more storage capacity on smaller clusters.

Bring Your Own Keys (BYOK): VMC Now Includes VM Encryption

VMware Cloud on AWS now supports customer-managed VM Encryption through an external KMIP-compliant Key Management Systems (KMS). What does that mean? You can now use your own keys for workload VM encryption – while the VMC control plane continues to use the AWS KMS (managed by Broadcom) for vSAN encryption.

VM Hardware Version 21

VM Hardware Version 21 is pretty cool, offering support for:

  • 256 Disks per VM – Massive storage capacity through 64 disks across 4 vNVMe adapters;
  • NVMe 1.3 – Enhanced performance for Windows 11 and Windows Server 2022 deployments.
  • NVMe for Windows Server Failover Clustering (WSFC) – High-performance shared storage for mission-critical clustered applications.
  • Latest Guest OS Support – Compatibility with RHEL 10, Oracle Linux 10, Debian 13, and FreeBSD 15.

The blog post has an excellent comparison of Version 20 and Version 21.

VMware Tools 12.5.4

VMware Tools 12.5.4 offers improved driver compatibility, enhanced VM performance, and provides better integration with the underlying VMC infrastructure.


Thoughts

Software updates aren’t always headlining news, but support for ESA on VMC (finally) is news that’s sure to make quite a few customers happy. I’ve no doubt they’re sick of hearing how cool it is from their on-premises counterparts and are keen to be part of the action. The updates to VMware Tools and VM Hardware version support are also minor, but important updates to the platform.

VMware Cloud on AWS – TMCHAM – Part 15 – Hosts and Subscriptions

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to do a short post on hosts and subscriptions on the VMware-managed VMware Cloud on AWS platform. It might seem like a simple thing, but it can be confusing for customers who are new to the service.


Definitions

Subscriptions

A subscription entitles you to run a host (or hosts) of a particular type (I3en.metal or I4i.metal) in a particular Region. The SKU of the subscription you purchase determines what you can run. For example, if you’d like to run I4i.metal hosts in the Sydney Region, you would need to purchase the VMC-AWS-I4-APE product. One of these entitles you to one host, and so on. The minimum term is 12 months, and these can be co-termed for longer periods to coincide with other product subscriptions. It’s important to understand that particular hosts aren’t tied to particular subscriptions. The subscription is at an Organization level, and its availability is based on a Region and Host type. So if you had 12 I4i subscriptions, and 6 I4i hosts deployed in the Sydney Region, and six in the Singapore Region, you’d be good to go. What you couldn’t do is use those I4i subscriptions to cover your deployment of I3en hosts in Ireland, for example. For that you’d need the VMC-AWS-I3EN-CCR SKU.

Note also, and this is pretty important, “[I]f you have hosts in excess of your purchased subscriptions, whether through EDRS storage scale-outs or due to expired subscriptions, your access to the VMware Cloud on AWS service and your SDDCs may be paused until the overconsumption is resolved. After 48 hours of excess usage, you will lose access to your SDDC(s) and workloads until you purchase sufficient subscriptions, and soon after that, your SDDC(s) will be irrevocably deleted”.

What’s In The Box?

So what do you get with VMware Cloud on AWS subscriptions? You get access to the following components on a per host basis:

  • A Software-Defined Data Centre (SDDC), consisting of:
    • AWS EC2 bare metal servers (I3en or I4i)
    • VMware vSphere
    • VMware vCenter Server
    • VMware NSX
    • VMware vDefend Gateway and Distributed Firewall (formerly NSX) – note that vDefend Advanced Threat Protection is sold separately.
    • VMware vSAN
    • VMware HCX
  • Self-service provisioning of SDDCs from the VMware Cloud Console at vmc.broadcom.com.
  • Maintenance, patching, and upgrades of the SDDC, performed by VMware by Broadcom

Note that License Portability is not supported with VMware Cloud on AWS.


Thoughts

The key thing to remember with subscriptions is that you need to buy subscriptions that match the host type and Region you’ll be deploying into. And you’ll need at least two to get started.

VMware Cloud on AWS – What’s New – December 2025

I posted last month about what’s new in VMware Cloud on AWS, particularly as it related to stretched cluster and HCX enhancements. The team has been working hard on some more new features, and I thought I’d cover them off briefly here. More detail can be found in the VMware Cloud on AWS Release Notes are here, and there’s a great blog post from the team here.


What’s New?

New Host Usage Report API

Have you been wondering what’s going on with resources in your VMC on AWS environment? Wonder no more. All the cool cloud kids are using APIs, and VMC on AWS is no different. Now you can retrieve daily host usage reports for any date range and filter by region, instance type, SKU, and other attributes – all via the API. There’s no need to call me and ask for a report on what’s happening, nor do you need to log a ticket to get access to the information. Here’s what a sample query looks like.

curl -H 'Authorization: <value>' https://{api_host}/api/activityanalytic/{org_id}/hosts/{freq}/usage-report?start_date=value&end_date=v

Check out the documentation here.

Redesigned VMware Cloud on AWS UI

The VMware Cloud on AWS UI has also had a facelift, and the interface is more streamlined and easier to navigate. You can access it at https://vmc.broadcom.com.

VMC Sizer & Cluster Conversion Updates

Ever since I started working with VMware Cloud on AWS, I’ve been a huge fan of the VMC Sizer tool. It’s so much better than trying to build solution estimates with a spreadsheet and a dream. If you’re an existing I3.metal customer, you’ve likely (hopefully) been planning a migration to I3en.metal or I4i.metal nodes. The conversion estimates can be a bit of a mystery, and have frequently required involving people like me and folks from the SRE team to provide these estimates. The product team has been working to make the process more streamlined, while giving customers improved visibility into why the numbers are the way they are. The output from sizing estimates now provides clear reasoning behind why a specific number of hosts is required, and this is based on 6 elements (compute, memory, storage utilisation (with both conservative and aggressive options), vSAN storage policies, and NSX Edges). It’s never been a simple matter of saying two I3.metal hosts equals one I4i.metal host, and now the sizer output reflects this more clearly.

The following constraints should be noted:

  • Final host counts and sizing will be validated during the actual cluster conversion. Sometimes you end up with more, sometimes you end up with fewer hosts.
  • Customers should re-run sizing evaluations after any significant configuration, resource, or other changes. Please don’t add another 30TiB workload to your cluster and expect the same result.
  • No RAID policy changes are made during conversion. This is especially notable if you’re using custom storage policies in your environment.
  • Subscription estimates provided as part of this workflow are for planning purposes only and do not represent guaranteed final requirements.
  • Actual subscription needs may be higher than estimated, requiring additional subscription purchase post-conversion. You’re given a small window to make good on this.
  • Refunds or subscription reductions will not be provided if estimates exceed actual needs.


Thoughts

As I mentioned in my previous post, VMware Cloud on AWS is not going anywhere, and the product and engineering teams continue to innovate and work hard to ensure that users get the best value from their investment in the VMware Cloud on AWS solution. The Host Usage Report is extremely useful, and for those customers concerned about cluster conversions, the improvements to the VMC Sizer should improve the confidence in the sizing process.

Amazon Web Services – Elastic VMware Service – A Few Notes …

Amazon Web Services (AWS) recently announced the general availability of its Elastic VMware Service (EVS). This is a brief post covering what the service is, how it can be consumed, and why it might be of interest.


What Is It?

EVS is a service that provides the ability to run VMware Cloud Foundation (5.2.1) on AWS bare-metal instances (specifically I4i.metal). It’s a by-the-book consolidated architecture (running management and workload domains together), and contains the following VCF management components:

  • ESXi hosts;
  • vCenter Server instance;
  • SDDC Manager;
  • vSAN datastore;
  • Three-node NSX Manager cluster;
  • vSphere cluster; and
  • NSX Edge cluster.

Storage is provided by vSAN (and selected third-party storage integrations), with two discrete network layers being delivered: the Amazon VPC and the VMware NSX overlay network. You can read more about the architecture here.

To consume the service, you’ll need 4 nodes to get started, along with at least 2 VPC Route Servers, and AWS Enterprise Support. There’s a pricing calculator on the AWS website. You’ll also need to procure VCF licensing from Broadcom or an authorised reseller.


Where Is It Available?

The initial launch Regions are:

  • US East (North Virginia)
  • US East (Ohio)
  • US West (Oregon)
  • Asia Pacific (Tokyo)
  • Europe (Frankfurt)
  • Europe (Ireland)

Availability in more Regions is planned for the future.

Other Considerations

Storage

You can leverage NetApp’s FSx for NetApp ONTAP service to provide additional storage for the cluster. There’s some useful guidance here and here. If you like it more orange, Pure Storage’s Cloud Block Store is also available for use with EVS. You can read that announcement here.

Clusters

Cluster sizes are currently limited to between 4 (minimum) and 16 (maximum) nodes. There is currently no support for stretched clusters. This will likely change in the future.

Add-ons

Services that VMware Cloud on AWS users may be familiar with, such as vDefend Advanced Threat Protection, and VMware Live Cyber Recovery, are not currently available with EVS.

Planning and Deployment

Much like VMC on AWS (and most other cloud service deployments, for that matter), there’s a bit of planning you’ll need to do before you jump on the console. There’s a handy checklist that takes you through all of the requirements here. It’s also worth noting that, unlike VMC on aWS, this isn’t a managed service, so some of the VPC constructs you see with VMC on AWS aren’t used with EVS. For example, there’s no shadow VPC deployed for EVS – it’s all done out of the customer account. And features like EDRS aren’t available, you need to manage your capacity yourself, in much the same way as you would do with an on-premises VCF deployment.


Thoughts

EVS is the same as VMC on AWS in the sense that it’s running VMware software on top of AWS bare metal servers. There are plenty of differences though, some of which I’ve covered above. I imagine many of the constraints around additional product integrations and scalability will be removed in the near future as the product evolves, and we’ll no doubt see some changes when it comes to partners offering managed services wrapped in with EVS. It’s been a while coming, but now that it’s here, I’m interested to see how the market responds. There are probably plenty of questions I haven’t answered, but there’s a useful FAQ document here.

VMware Cloud on AWS – TMCHAM – Part 14 – Stretched Clusters and Disaster Recovery

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to cover some of the things to consider when looking at Disaster Recovery (DR) and availability solutions on the VMware-managed VMware Cloud on AWS platform. It might seem like basic stuff if you’re already using the platform, but there are plenty of customers I talk to that are struggling to distinguish between DR, data availability, and periodic data protection in a VMware Cloud context.


Terminology

I’m cheating a little here and re-using some of my older content, but I think it still holds up.

  • Disaster Recovery – Disaster Recovery is the ability to recover applications after a major event (think flood, fire, data centre is now a hole in the ground). This normally involves a failover of workloads from one DC to another in an orchestrated fashion. In a VMware context, you would use VMware Live Recovery (Site or Cyber, depending on the environment).
  • Disaster Avoidance – Disaster avoidance “is an anticipatory strategy that is in place in order to prevent any such instance of data breach or losses. It is a defensive, proactive approach to keeping data safe” (I’m quoting this from a great blog post on the topic here). In a VMware context, this would be a stretched cluster using vSAN on VMware Cloud Foundation or in VMC on AWS.
  • Periodic Data Protection – This is the kind of data protection activity we normally associate with “backups”. It is usually a daily activity (or perhaps as frequent as hourly) and the data is normally used for ad-hoc data file recovery requests. Some people use their backup data as an archive. They’re bad people and shouldn’t be trusted. You should consider PDP as separate to DA or DR solutions.


So How Do I Best Protect My Workloads? (Part 1)

Understand Your Workloads

You need to understand how your applications work. And you need to understand what talks to them and what they talk to. There are plenty of ways of doing this, including a variety if applications available that scan network traffic and draw pretty pictures of data flows for you. From experience, there’s a very good chance you won’t get this information by reading current documentation, because it won’t be current.

You need to understand how important your applications are to you. Do you need to recover them immediately if something goes wrong? Can you do without them for a few hours? A few days? How much data can you afford to lose? All of it? (in which case why do you still have this data sitting around?). None of it? Some of it? You need to be disciplined and thorough in your assessment of your workloads and what they mean to your business, because protecting them or recovering them can be an expensive exercise.

Understand What Scares You Most

What do you call a disaster? Is it a data centre turning into a hole in the ground? Do you run most of your workloads in an area prone to natural disasters? Or are you more worried about people in hoodies breaking into your infrastructure and encrypting it and your data protection infrastructure? (Hot tip: you absolutely should be worried about this). You need to be fairly paranoid about the scenarios you’re trying to protect your environment from. No one thought it was a problem keeping workloads in two buildings in New York until it was. At the same time, you’ll need to introduce some pragmatism into your planning. I’ve had customers ask me what they could do if all of the Sydney Region was wiped out (not just the AWS deployment, but the whole city). Could they recover data to Melbourne? Sure. Would they have any staff left to do it? Or want to do it? Depending on the nature of the disaster, the technical aspects of disaster recovery are going to be the easy bits. You still need to make sure the people and process bit is covered.

Who Can Help You? 

Do you want to handle any recovery activities yourself when things go bang? Or are you happy to let someone else do the heavy lifting for you? Some folks don’t trust outsiders to do “important” things, like recover workloads, whilst other organisations would consume absolutely everything as a service if it was an option.

How Much Can You Spend?

You need to answer the questions above before you can answer how much you’re willing to spend on one (or more) solutions to help keep your workloads protected. If your apps aren’t that important, or your business can continue to run without access to these apps for a period of time, then you’re going to be less inclined to go for the “platinum” solution. But if you’re whole business relies on applications being available 24/7/365, then you’re hopefully more understanding that you’ll need to invest.


So How Do I Best Protect My Workloads? (Part 2)

Data Availability with VMware Cloud on AWS

As I mentioned earlier in this post, if you’re looking to provide data availability for your workloads on VMware Cloud on AWS, you should be looking at deploying a stretched cluster solution. In short, stretched clusters in VMware Cloud on AWS are designed to protect against an AWS availability zone (AZ) failure. There’s a feature brief available here that goes into more depth on the solution. Key things to note are that the vSAN stretched cluster is deployed across 3 AZs (2 workload, 1 witness). So you could have 3 hosts in one AZ, 3 in another, and VMware deploys a witness node in the third site as part of the deployment. From the document, “vSAN Fault Domains are configured to inform vSphere and vCenter which Hosts reside in which AZ. Each Fault Domain is named after the AZ it resides within to increase clarity. Logical networks are also extended using NSX to support workload mobility across the two AWS availability zones”. You also have the option to keep data using various vSAN storage policies, including:

  • Dual-site mirroring (stretched cluster)
  • None – Keep data on primary (stretched cluster)
  • None – Keep data on secondary (stretched cluster)

Why would you not just mirror everything? Cost. Some applications simply don’t need that level of resilience, but it’s too complicated to deploy multiple SDDCs to support multiple deployment topologies (you can’t have a mix of single AZ and stretched clusters in the same SDDC), so customers can keep a mix of workloads in the same deployment. Note also that external storage solutions (like FSx for NetApp ONTAP) aren’t supported for use with stretched clusters. vSphere HA will restart the VM on the surviving AZ if a site failure is detected. There’s a short video on YouTube that covers a stretched cluster deployment and is worth looking at.

Disaster Recovery with VMware Cloud on AWS

I’ve covered VMware Live Cyber Recovery (and its predecessor, VMware Cloud Disaster Recovery) on this blog before. It’s a great solution to protect on-premises, GCVE, and VMware Cloud on AWS workloads.  It provides protection to a secure cloud filesystem with a Recovery Point Objective as low as 15 minutes, the ability to perform guided ransomware recovery in an isolated environment, and SaaS-based recovery automation. The kind of things you want to consider when evaluating the suitability of VLCR to your needs would be:

  • Recovery Point Objective – the maximum amount of time in which data may have been permanently lost during an incident. VLCR goes down to 15 minutes, but if you need lower than that you need to look at other architectures.
  • Scalability – how many Virtual Machines and how much storage are you trying to protect? And how quickly do you want to recover it? And where do you want to recover it to? Some folks don’t like VMware Cloud on AWS being the only recovery option, but VMware has announced “plans to enhance VMware Live Recovery support for Google Cloud VMware Engine (GCVE) as a cyber and disaster recovery (DR) site, for both on-premises as well as GCVE environments“. You can check out the configuration maximums for VMware solutions here.
  • Networking and security – how will you access your recovery workloads? Will you use HCX to have stretched networks between your protected sites and your recovery site? What does that look like for your core networking infrastructure? Is your CISO happy to recover stuff onto a cloud platform? There are many things you’ll need to work through internally to ensure people are comfortable. I’d also recommend you go with a pilot light deployment as opposed to an on-demand solution. While the pilot light option seems more expensive, it will save you when something goes wrong and you’ve already tested your deployment.
  • Other Considerations – there’s a bunch of info in the legacy VCDR Release Notes that highlight some of the constraints to be aware of from an architectural standpoint, and understanding some of these (like the ability to protect stretched clusters, but not recover to stretched clusters) is key to ensuring your architecture will work when you push the button. And one point that is often missed by folks looking at VLCR for the first time is that, as the recovery SDDC is just a VMware Cloud on AWS deployment, you can use it for other workloads in the meantime, like dev/test stuff, when you’re not in a recovery situation.

Periodic Data Protection with VMware Cloud on AWS

There are a tonne of different things you can do here, and I’d be naive to suggest that I could cover them all effectively in this post. To use periodic data protection solutions with VMware Cloud on AWS, you should check out this KB article, and work with your data protection vendor to ensure that the solution has been tested and works on VMware Cloud on AWS. I’ve encountered a few situations where the vendor has assumed that VMware Cloud on AWS works the same way as VMware on-premises, and with the same ability to do silly things with privileged access to ESXi hosts and things of that nature. There aren’t a lot of restrictions in place, but there are some important ones, like the aforementioned limits on direct host access, restricted account privileges, and so on. Just make sure you test it before you buy it. I’ll try and cover some of the scenarios that do and don’t work in a future post (without naming too many names).


Conclusion

I’m sticking with solutions available with VMware Cloud on AWS in this post, mainly because that’s what I’m talking to people about on a daily basis. But there’s plenty here that can be applied more generically to a variety of infrastructure solutions. You’ll have the same questions you’ll need to ask when it comes to protecting workloads on-premises (regardless of your choice of hypervisor), and you’ll need to make some hard decisions ab out what you want to protect depending on the value of what your workloads deliver to the business, and the available budget. You might also need to consider doing a combination of all three options, depending on the importance of the data / workloads you’re looking after. I’d always pick stretched clusters to keep my workloads up and available, but that won’t help me if some hacker decides to dump ransomware in my environment and encrypt all of my stuff. But if I need to go back 24 months to retrieve some file for an auditor, I wouldn’t use VMware Live Cyber Recovery for that. I should also mention that you should be using application-level protection as your first option for application resilience too. This other stuff is all infrastructure level, and potentially not as elegant, depending on your applications. But that doesn’t mean you can’t combine both methods. Unfortunately, there’s no one magical fix for this problem, but with a bit of planning, and some critical evaluation, you can protect your workloads against all manner of bad situations. And if you can’t do everything, at least do something, but just make sure people in your business understand the difference between the two. And remember, you’re only as good as your last recovery.

VMware Live Cyber Recovery Link-O-Rama

Background

It’s been just over six months since VMware Live Recovery was announced. This is an umbrella product name for VMware Live Site Recovery (formerly known as Site Recovery Manager) and VMware Live Cyber Recovery (formerly known as VMware Cloud Disaster Recovery and Ransomware Recovery). Like many of the changes at VMware this year, this is a move designed to streamline the disaster recovery solutions being made available for VMware Cloud Foundation, and to make it simpler for you to choose which product works best for you.

To that end, I’ve put together a series of links from the documentation that I’ve found useful when talking with customers about VMware Live Cyber Recovery in particular. I figured if my customers were asking about these things, someone else might find the answers useful too. This isn’t comprehensive, but hopefully it’s of some use.


Link-O-Rama

Maximum Configs

Here are the current configuration maximums for VMware Live Site Recovery, VMware Live Cyber Recovery, and local vSAN snapshots. Why would you need to know these? There are useful things to know that differentiate the products, such as the recovery point objective values, virtual machine limits, and so on. Remember, these should be treated as limits, not targets, and if you have an environment that exceeds these limits, reach out to your account team to talk about it.

Networking Considerations

  • Does your security team want to know more about the Cyber Recovery (formerly DRaaS) connector? Check out this document.
  • Can you use Direct Connect instead of clobbering my Internet feed? Yes, here’s how. Want to know more about AWS Direct Connect (useful if you’re new to AWS)? This article should help.
  • What holes do you need to punch through my firewall for things like support and telemetry data uploads? This article on Service Public IP Addresses should help some.
  • Can you throttle the bandwidth that the replication uses? Yes, you can. The documentation is here.
  • Need to configure different IP addresses for your recovered virtual machines. This documentation should help.

How Do I Use It?

You can find (a slightly dated) copy of the VMware Cloud Disaster Recovery Admin Guide in PDF format here. Some things have changed with the switch to VMware Live Cyber Recovery, but the fundamentals remain the same, and it’s handy to have a downloadable copy of the admin guide, particularly when you’re in a situation where your data centre is on fire and your Internet connection is a melted mess.

Want to get a better feel for how VMware Live Cyber Recovery handles? Check out this Hands-on Lab.

Release Notes

The overall release notes for VMware Live Recovery are available here. You’ll see interesting bits of news, such as “VMware Cloud Director Availability is now part of VMware Live Recovery”. You can also drill down into the VMware Live Cyber Recovery documentation here, and the VMware Live Site Recovery 9.0 documentation can be found here. If you need to dig through some historical release notes (or just want to take a trip down memory lane), you can view the VMware Cloud Disaster Recovery release notes archive here.

But I Have More Questions

  • There’s a great set of Frequently Asked Questions on VMware Live Recovery in PDF format that can be found here.
  • How do you know if you need disaster recovery or ransomware recovery (or both)? This is a great article covering some of the considerations that you’ll need to think about.
  • Are you looking at backup solutions for VMware Cloud on AWS? This is a comprehensive article on using third-party backup and recovery tools with VMware Cloud on AWS.
  • Looking to leverage VMware Site Recovery on VMware Cloud on AWS? It has gone away, and you should consider moving to VMware Live Cyber Recovery.
  • Wondering about the overall security of the VMware Live Cyber Recovery product? The Cloud Security Alliance performed a VCDR Assessment that you can access here.


Conclusion

And that’s about it. I’ve published a few posts on this weblog covering VMware Cloud Disaster Recovery in the past, and you can find them here. While some of the screens might look a little different now, the vibe remains unchanged. If you have questions that I haven’t answered here, feel free to reach out and I’ll see if I can help.

VMware Cloud on AWS – TMCHAM – Part 13 – Delete the SDDC

*Update* 2025/01/30 – The VMware docs site has been moved to Broadcom’s Techdocs site. I won’t be updating all of the VMware links on this weblog, but this post will get the treatment.

Following on from my article on host removal, in this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to cover SDDC removal on the VMware-managed VMware Cloud on AWS platform. Don’t worry, I haven’t lost my mind in a post-acquisition world. Rather, this is some of the info you’ll find useful if you’ve been running a trial or a proof of concept (as opposed to a pilot) deployment of VMware Cloud Disaster Recovery (VCDR) and / or VMware Cloud on AWS and want to clean some stuff up when you’re all done.


Process

Firstly, if you’re using VCDR and want to deactivate the deployment, the steps to perform are outlined here, and I’ve copied the main bits from that page below.

  1. Remove all DRaaS Connectors from all protected sites. See Remove a DRaaS Connector from a Protected Site (new link here).
  2. Delete all recovery SDDCs. See Delete a Recovery SDDC (new link here).
  3. Deactivate the recovery region from the Global DR Console. (Do this step last.) See Deactivate a Recovery Region (new link here). Usage charges for VMware Cloud DR are not stopped until this step is completed.

Funnily enough, as I was writing this, someone zapped our lab for reasons. So this is what a Region deactivation looks like in the VCDR UI.

Note that it’s important you perform these steps in that order, or you’ll have more cleanup work to do to get everything looking nice and tidy. I have witnessed firsthand someone doing it the other way and it’s not pretty. Note also that if your Recovery SDDC had services such as HCX connected, you should hold off deleting the Recovery SDDC until you’ve cleaned that bit up.

Secondly, if you have other workloads deployed in a VMware Cloud on AWS SDDC and want to remove a PoC SDDC, there are a few steps that you will need to follow.

If you’ve been using HCX to test migrations or network extension, you’ll need to follow these steps (new link here) to remove it. Note that this should be initiated from the source side, and your HCX deployment should be in good order before you start (site pairings functioning, etc). You might also wish to remove a vCenter Cloud Gateway, and you can find information on that process here (new link here).

Finally, there are some AWS activities that you might want to undertake to clean everything up. These include:

  • Removing VIFs attached to your AWS VPC.
  • Deleting the VPC (this will likely be required if your organisation has a policy about how PoC deployments  are managed).
  • Tidy up and on-premises routing and firewall rules that may have been put in place for the PoC activity.

And that’s it. There’s not a lot to it, but tidying everything up after a PoC will ensure that you avoid any unexpected costs popping up in the future.

VMware Cloud on AWS – TMCHAM – Part 12 – Host Removal

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to cover host removal on the VMware-managed VMware Cloud on AWS platform. This is a fairly brief post, as there’s not a lot to say about the process, but I’ve had enough questions about that I thought it was worth covering.


Background

I’ve written about Elastic DRS (EDRS) in VMware Cloud on AWS previously. It’s something you can’t turn off, and the Baseline policy does a good job of making sure you don’t get in hot water from a storage perspective. That said, there might be occasions where you want to remove a host or two to scale in your cluster manually. This might happen after a cluster conversion, or you may have had a rapid scale out event and you have now removed whatever workloads caused that scale out event to occur.


Process

The process to remove a host is documented here. Note that it is a sequential process, with one host being removed at a time. Depending on the number of hosts in your cluster, you may need to adjust your storage and fault tolerance policies as well. To start the process, go to your cloud console and select the SDDC you want to remove the hosts from. If there’s only one cluster, you can click on Remove Hosts under Actions. If there are multiple clusters in the SDDC, you’ll need to select the cluster you want to remove the host from.

You’ll then be advised that you need to understand what you’re doing (and acknowledge that), and you may be advised to change your default storage policies as well. More info on those policies is here.

Once you kick off the process, the cluster will be evaluated to ensure that removing hosts will not violate the applicable EDRS policies. VMs will be migrated off the host when it’s put into maintenance mode, and billing will be stopped for that host.

And that’s it. Pretty straightforward.

VMware Cloud on AWS – What’s New – February 2024

It’s been a little while since I posted an update on what’s new with VMware Cloud on AWS, so I thought I’d share some of the latest news.


M7i.metal-24xl Announced

It’s been a few months since it was announced at AWS re:Invent 2023, but the M7i.metal-24xl (one of the catchier host types I’ve seen) is going to the change the way we approach storage-heavy VMC on AWS deployments.

What is it?

It’s a host without local storage. There are 48 physical cores (96 logical cores with Hyper-Threading enabled). It has 384 GiB memory. The key point is that there are flexible NFS storage options to choose from – VMware Cloud Flex Storage or Amazon FSx for NetApp ONTAP. There’s support for up to 37.5 Gbps networking speed, and it supports always-on memory encryption using Intel Total Memory Encryption (TME).

Why?

Some of the potential use cases for this kind of host type are as follows:

  • CPU Intensive workloads
    • Image processing
    • Video encoding
    • Gaming servers
  • AI/ML Workloads
    • Code Generation
    • Natural Language Processing
    • Classical Machine Learning
    • Workloads with limited resource requirements
  • Web and application servers
    • Microservices/Management services
    • Secondary data stores/database applications
  • Ransomware & Disaster Recovery
    • Modern Ransomware Recovery
    • Next-gen DR
    • Compliance and Risk Management

Other Notes

New (greenfield) customers can deploy the M7i.metal-24xl in the first cluster using 2-16 nodes. Existing (brownfield) customers can deploy the M7i.metal-24xl in secondary clusters in the same SDDC. In terms of connectivity, we recommend you take advantage of VPC peering for your external storage connectivity. Note that there is no support for multi-AZ deployments, nor is there support for single node deployments. If you’d like to know more about the M7i.metal-24xl, there’s an excellent technical overview here.


vSAN Express Storage Architecture on VMware Cloud on AWS

SDDC Version 1.24 was announced in November 2023, and with that came support for vSAN Express Storage Architecture (ESA) on VMC on AWS. There’s some great info on what’s included in the 1.24 release here, but I thought I’d focus on some of the key constraints you need to look at when considering ESA in your VMC on AWS environment.

Currently, the following restrictions apply to vSAN ESA in VMware Cloud on AWS:
  • vSAN ESA is available for clusters using i4i hosts only.
  • vSAN ESA is not supported with stretched clusters.
  • vSAN ESA is not supported with 2-host clusters.
  • After you have deployed a cluster, you cannot convert from vSAN ESA to vSAN OSA or vice versa.
So why do it? There are plenty of reasons, including better performance, enhanced resource efficiency, and several improvements in terms of speed and resiliency. You can read more about it here.

VMware Cloud Disaster Recovery Updates

There have also been some significant changes to VCDR, with the recent announcement that we now support a 15-minute Recovery Point Objective (down from 30 minutes). There have also been a number of enhancements to the ransomware recovery capability, including automatic Linux security sensor installation in the recovery workflow (trust me, once you’ve done it manually a few times you’ll appreciate this). With all the talk of supplemental storage above, it should be noted that “VMware Cloud DR does not support recovering VMs to VMware Cloud on AWS SDDC with NFS-mounted external datastores including Amazon FSx for NetApp datastores, Cloud Control Volumes or VMware Cloud Flex Storage”. Just in case you had an idea that this might be something you want to do.


Thoughts

Much of the news about VMware has been around the acquisition by Broadcom. It certainly was news. In the meantime, however, the VMware Cloud on AWS product and engineering teams have continued to work on releasing innovative features and incremental improvements. The encouraging thing about this is that they are listening to customers and continuing to adapt the solution architecture to satisfy those requirements. This is a good thing for both existing and potential customers. If you looked at VMware Cloud on AWS three years ago and ruled it out, I think it’s worth looking at again.