VMware Cloud on AWS – TMCHAM – Part 16 – Remove External Datastores

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to do a (really) short post on removing external datastores on the VMware-managed VMware Cloud on AWS platform. It might seem like a simple thing, but it can be confusing for customers who haven’t done it before.


The Problem

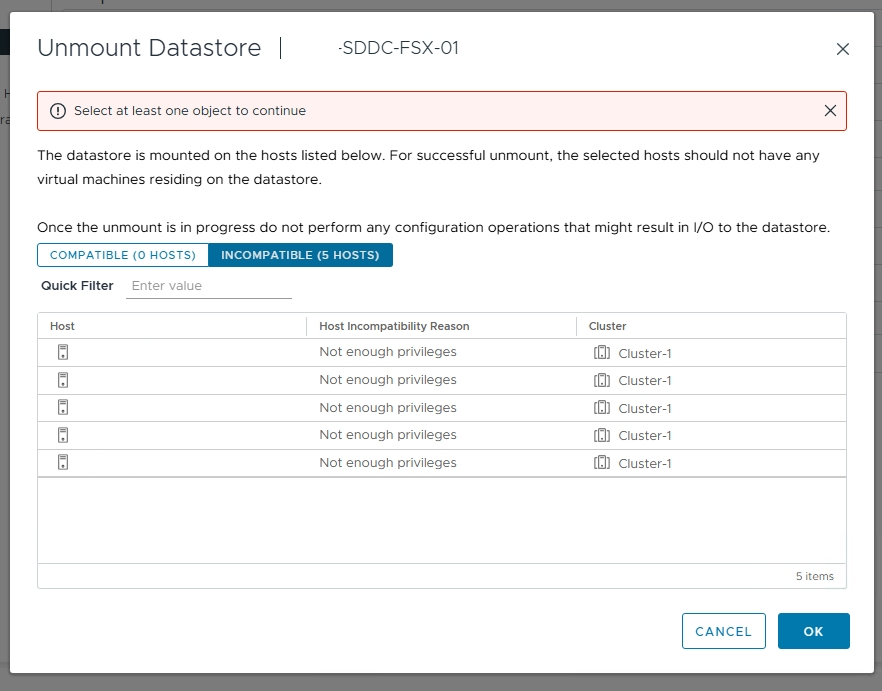
If you’ve used an external datastore (either FSx for NetApp ONTAP or the artist formerly known as VMware Cloud Flex Storage) with your SDDC, you’ll know that management of the connection of the datastores to your SDDC is done via the Cloud Console, and not via vCenter. There might come a time when you want to remove that storage, either because you’ve bought more nodes and want to use vSAN, or you’re possibly shrinking your footprint. Whatever the reason, if you do try to remove the datastore via vCenter (assuming you’ve removed your workloads from the datastore), you’ll get an error about insufficient privileges. At first it might seem like it’s because you have VMs still present on the datastore (and if this is the case, contact Global Support to help you if you can’t find them). It’s more likely, however, that you’re not in the right place to do this activity.


The Solution

The solution is simple. In the VMware Cloud Console, go to the Storage tab of the SDDC you want to remove the datastore from, and click on Detach Datastore. And that’s it. It won’t work if you’ve got workloads running there, so make sure you’ve cleaned everything up / moved it somewhere else before you attempt this one.

VMware Cloud on AWS – TMCHAM – Part 15 – Hosts and Subscriptions

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to do a short post on hosts and subscriptions on the VMware-managed VMware Cloud on AWS platform. It might seem like a simple thing, but it can be confusing for customers who are new to the service.


Definitions

Subscriptions

A subscription entitles you to run a host (or hosts) of a particular type (I3en.metal or I4i.metal) in a particular Region. The SKU of the subscription you purchase determines what you can run. For example, if you’d like to run I4i.metal hosts in the Sydney Region, you would need to purchase the VMC-AWS-I4-APE product. One of these entitles you to one host, and so on. The minimum term is 12 months, and these can be co-termed for longer periods to coincide with other product subscriptions. It’s important to understand that particular hosts aren’t tied to particular subscriptions. The subscription is at an Organization level, and its availability is based on a Region and Host type. So if you had 12 I4i subscriptions, and 6 I4i hosts deployed in the Sydney Region, and six in the Singapore Region, you’d be good to go. What you couldn’t do is use those I4i subscriptions to cover your deployment of I3en hosts in Ireland, for example. For that you’d need the VMC-AWS-I3EN-CCR SKU.

Note also, and this is pretty important, “[I]f you have hosts in excess of your purchased subscriptions, whether through EDRS storage scale-outs or due to expired subscriptions, your access to the VMware Cloud on AWS service and your SDDCs may be paused until the overconsumption is resolved. After 48 hours of excess usage, you will lose access to your SDDC(s) and workloads until you purchase sufficient subscriptions, and soon after that, your SDDC(s) will be irrevocably deleted”.

What’s In The Box?

So what do you get with VMware Cloud on AWS subscriptions? You get access to the following components on a per host basis:

  • A Software-Defined Data Centre (SDDC), consisting of:
    • AWS EC2 bare metal servers (I3en or I4i)
    • VMware vSphere
    • VMware vCenter Server
    • VMware NSX
    • VMware vDefend Gateway and Distributed Firewall (formerly NSX) – note that vDefend Advanced Threat Protection is sold separately.
    • VMware vSAN
    • VMware HCX
  • Self-service provisioning of SDDCs from the VMware Cloud Console at vmc.broadcom.com.
  • Maintenance, patching, and upgrades of the SDDC, performed by VMware by Broadcom

Note that License Portability is not supported with VMware Cloud on AWS.


Thoughts

The key thing to remember with subscriptions is that you need to buy subscriptions that match the host type and Region you’ll be deploying into. And you’ll need at least two to get started.

VMware Cloud on AWS – TMCHAM – Part 14 – Stretched Clusters and Disaster Recovery

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to cover some of the things to consider when looking at Disaster Recovery (DR) and availability solutions on the VMware-managed VMware Cloud on AWS platform. It might seem like basic stuff if you’re already using the platform, but there are plenty of customers I talk to that are struggling to distinguish between DR, data availability, and periodic data protection in a VMware Cloud context.


Terminology

I’m cheating a little here and re-using some of my older content, but I think it still holds up.

  • Disaster Recovery – Disaster Recovery is the ability to recover applications after a major event (think flood, fire, data centre is now a hole in the ground). This normally involves a failover of workloads from one DC to another in an orchestrated fashion. In a VMware context, you would use VMware Live Recovery (Site or Cyber, depending on the environment).
  • Disaster Avoidance – Disaster avoidance “is an anticipatory strategy that is in place in order to prevent any such instance of data breach or losses. It is a defensive, proactive approach to keeping data safe” (I’m quoting this from a great blog post on the topic here). In a VMware context, this would be a stretched cluster using vSAN on VMware Cloud Foundation or in VMC on AWS.
  • Periodic Data Protection – This is the kind of data protection activity we normally associate with “backups”. It is usually a daily activity (or perhaps as frequent as hourly) and the data is normally used for ad-hoc data file recovery requests. Some people use their backup data as an archive. They’re bad people and shouldn’t be trusted. You should consider PDP as separate to DA or DR solutions.


So How Do I Best Protect My Workloads? (Part 1)

Understand Your Workloads

You need to understand how your applications work. And you need to understand what talks to them and what they talk to. There are plenty of ways of doing this, including a variety if applications available that scan network traffic and draw pretty pictures of data flows for you. From experience, there’s a very good chance you won’t get this information by reading current documentation, because it won’t be current.

You need to understand how important your applications are to you. Do you need to recover them immediately if something goes wrong? Can you do without them for a few hours? A few days? How much data can you afford to lose? All of it? (in which case why do you still have this data sitting around?). None of it? Some of it? You need to be disciplined and thorough in your assessment of your workloads and what they mean to your business, because protecting them or recovering them can be an expensive exercise.

Understand What Scares You Most

What do you call a disaster? Is it a data centre turning into a hole in the ground? Do you run most of your workloads in an area prone to natural disasters? Or are you more worried about people in hoodies breaking into your infrastructure and encrypting it and your data protection infrastructure? (Hot tip: you absolutely should be worried about this). You need to be fairly paranoid about the scenarios you’re trying to protect your environment from. No one thought it was a problem keeping workloads in two buildings in New York until it was. At the same time, you’ll need to introduce some pragmatism into your planning. I’ve had customers ask me what they could do if all of the Sydney Region was wiped out (not just the AWS deployment, but the whole city). Could they recover data to Melbourne? Sure. Would they have any staff left to do it? Or want to do it? Depending on the nature of the disaster, the technical aspects of disaster recovery are going to be the easy bits. You still need to make sure the people and process bit is covered.

Who Can Help You? 

Do you want to handle any recovery activities yourself when things go bang? Or are you happy to let someone else do the heavy lifting for you? Some folks don’t trust outsiders to do “important” things, like recover workloads, whilst other organisations would consume absolutely everything as a service if it was an option.

How Much Can You Spend?

You need to answer the questions above before you can answer how much you’re willing to spend on one (or more) solutions to help keep your workloads protected. If your apps aren’t that important, or your business can continue to run without access to these apps for a period of time, then you’re going to be less inclined to go for the “platinum” solution. But if you’re whole business relies on applications being available 24/7/365, then you’re hopefully more understanding that you’ll need to invest.


So How Do I Best Protect My Workloads? (Part 2)

Data Availability with VMware Cloud on AWS

As I mentioned earlier in this post, if you’re looking to provide data availability for your workloads on VMware Cloud on AWS, you should be looking at deploying a stretched cluster solution. In short, stretched clusters in VMware Cloud on AWS are designed to protect against an AWS availability zone (AZ) failure. There’s a feature brief available here that goes into more depth on the solution. Key things to note are that the vSAN stretched cluster is deployed across 3 AZs (2 workload, 1 witness). So you could have 3 hosts in one AZ, 3 in another, and VMware deploys a witness node in the third site as part of the deployment. From the document, “vSAN Fault Domains are configured to inform vSphere and vCenter which Hosts reside in which AZ. Each Fault Domain is named after the AZ it resides within to increase clarity. Logical networks are also extended using NSX to support workload mobility across the two AWS availability zones”. You also have the option to keep data using various vSAN storage policies, including:

  • Dual-site mirroring (stretched cluster)
  • None – Keep data on primary (stretched cluster)
  • None – Keep data on secondary (stretched cluster)

Why would you not just mirror everything? Cost. Some applications simply don’t need that level of resilience, but it’s too complicated to deploy multiple SDDCs to support multiple deployment topologies (you can’t have a mix of single AZ and stretched clusters in the same SDDC), so customers can keep a mix of workloads in the same deployment. Note also that external storage solutions (like FSx for NetApp ONTAP) aren’t supported for use with stretched clusters. vSphere HA will restart the VM on the surviving AZ if a site failure is detected. There’s a short video on YouTube that covers a stretched cluster deployment and is worth looking at.

Disaster Recovery with VMware Cloud on AWS

I’ve covered VMware Live Cyber Recovery (and its predecessor, VMware Cloud Disaster Recovery) on this blog before. It’s a great solution to protect on-premises, GCVE, and VMware Cloud on AWS workloads.  It provides protection to a secure cloud filesystem with a Recovery Point Objective as low as 15 minutes, the ability to perform guided ransomware recovery in an isolated environment, and SaaS-based recovery automation. The kind of things you want to consider when evaluating the suitability of VLCR to your needs would be:

  • Recovery Point Objective – the maximum amount of time in which data may have been permanently lost during an incident. VLCR goes down to 15 minutes, but if you need lower than that you need to look at other architectures.
  • Scalability – how many Virtual Machines and how much storage are you trying to protect? And how quickly do you want to recover it? And where do you want to recover it to? Some folks don’t like VMware Cloud on AWS being the only recovery option, but VMware has announced “plans to enhance VMware Live Recovery support for Google Cloud VMware Engine (GCVE) as a cyber and disaster recovery (DR) site, for both on-premises as well as GCVE environments“. You can check out the configuration maximums for VMware solutions here.
  • Networking and security – how will you access your recovery workloads? Will you use HCX to have stretched networks between your protected sites and your recovery site? What does that look like for your core networking infrastructure? Is your CISO happy to recover stuff onto a cloud platform? There are many things you’ll need to work through internally to ensure people are comfortable. I’d also recommend you go with a pilot light deployment as opposed to an on-demand solution. While the pilot light option seems more expensive, it will save you when something goes wrong and you’ve already tested your deployment.
  • Other Considerations – there’s a bunch of info in the legacy VCDR Release Notes that highlight some of the constraints to be aware of from an architectural standpoint, and understanding some of these (like the ability to protect stretched clusters, but not recover to stretched clusters) is key to ensuring your architecture will work when you push the button. And one point that is often missed by folks looking at VLCR for the first time is that, as the recovery SDDC is just a VMware Cloud on AWS deployment, you can use it for other workloads in the meantime, like dev/test stuff, when you’re not in a recovery situation.

Periodic Data Protection with VMware Cloud on AWS

There are a tonne of different things you can do here, and I’d be naive to suggest that I could cover them all effectively in this post. To use periodic data protection solutions with VMware Cloud on AWS, you should check out this KB article, and work with your data protection vendor to ensure that the solution has been tested and works on VMware Cloud on AWS. I’ve encountered a few situations where the vendor has assumed that VMware Cloud on AWS works the same way as VMware on-premises, and with the same ability to do silly things with privileged access to ESXi hosts and things of that nature. There aren’t a lot of restrictions in place, but there are some important ones, like the aforementioned limits on direct host access, restricted account privileges, and so on. Just make sure you test it before you buy it. I’ll try and cover some of the scenarios that do and don’t work in a future post (without naming too many names).


Conclusion

I’m sticking with solutions available with VMware Cloud on AWS in this post, mainly because that’s what I’m talking to people about on a daily basis. But there’s plenty here that can be applied more generically to a variety of infrastructure solutions. You’ll have the same questions you’ll need to ask when it comes to protecting workloads on-premises (regardless of your choice of hypervisor), and you’ll need to make some hard decisions ab out what you want to protect depending on the value of what your workloads deliver to the business, and the available budget. You might also need to consider doing a combination of all three options, depending on the importance of the data / workloads you’re looking after. I’d always pick stretched clusters to keep my workloads up and available, but that won’t help me if some hacker decides to dump ransomware in my environment and encrypt all of my stuff. But if I need to go back 24 months to retrieve some file for an auditor, I wouldn’t use VMware Live Cyber Recovery for that. I should also mention that you should be using application-level protection as your first option for application resilience too. This other stuff is all infrastructure level, and potentially not as elegant, depending on your applications. But that doesn’t mean you can’t combine both methods. Unfortunately, there’s no one magical fix for this problem, but with a bit of planning, and some critical evaluation, you can protect your workloads against all manner of bad situations. And if you can’t do everything, at least do something, but just make sure people in your business understand the difference between the two. And remember, you’re only as good as your last recovery.

VMware Cloud on AWS – TMCHAM – Part 13 – Delete the SDDC

*Update* 2025/01/30 – The VMware docs site has been moved to Broadcom’s Techdocs site. I won’t be updating all of the VMware links on this weblog, but this post will get the treatment.

Following on from my article on host removal, in this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to cover SDDC removal on the VMware-managed VMware Cloud on AWS platform. Don’t worry, I haven’t lost my mind in a post-acquisition world. Rather, this is some of the info you’ll find useful if you’ve been running a trial or a proof of concept (as opposed to a pilot) deployment of VMware Cloud Disaster Recovery (VCDR) and / or VMware Cloud on AWS and want to clean some stuff up when you’re all done.


Process

Firstly, if you’re using VCDR and want to deactivate the deployment, the steps to perform are outlined here, and I’ve copied the main bits from that page below.

  1. Remove all DRaaS Connectors from all protected sites. See Remove a DRaaS Connector from a Protected Site (new link here).
  2. Delete all recovery SDDCs. See Delete a Recovery SDDC (new link here).
  3. Deactivate the recovery region from the Global DR Console. (Do this step last.) See Deactivate a Recovery Region (new link here). Usage charges for VMware Cloud DR are not stopped until this step is completed.

Funnily enough, as I was writing this, someone zapped our lab for reasons. So this is what a Region deactivation looks like in the VCDR UI.

Note that it’s important you perform these steps in that order, or you’ll have more cleanup work to do to get everything looking nice and tidy. I have witnessed firsthand someone doing it the other way and it’s not pretty. Note also that if your Recovery SDDC had services such as HCX connected, you should hold off deleting the Recovery SDDC until you’ve cleaned that bit up.

Secondly, if you have other workloads deployed in a VMware Cloud on AWS SDDC and want to remove a PoC SDDC, there are a few steps that you will need to follow.

If you’ve been using HCX to test migrations or network extension, you’ll need to follow these steps (new link here) to remove it. Note that this should be initiated from the source side, and your HCX deployment should be in good order before you start (site pairings functioning, etc). You might also wish to remove a vCenter Cloud Gateway, and you can find information on that process here (new link here).

Finally, there are some AWS activities that you might want to undertake to clean everything up. These include:

  • Removing VIFs attached to your AWS VPC.
  • Deleting the VPC (this will likely be required if your organisation has a policy about how PoC deployments  are managed).
  • Tidy up and on-premises routing and firewall rules that may have been put in place for the PoC activity.

And that’s it. There’s not a lot to it, but tidying everything up after a PoC will ensure that you avoid any unexpected costs popping up in the future.

VMware Cloud on AWS – TMCHAM – Part 12 – Host Removal

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to cover host removal on the VMware-managed VMware Cloud on AWS platform. This is a fairly brief post, as there’s not a lot to say about the process, but I’ve had enough questions about that I thought it was worth covering.


Background

I’ve written about Elastic DRS (EDRS) in VMware Cloud on AWS previously. It’s something you can’t turn off, and the Baseline policy does a good job of making sure you don’t get in hot water from a storage perspective. That said, there might be occasions where you want to remove a host or two to scale in your cluster manually. This might happen after a cluster conversion, or you may have had a rapid scale out event and you have now removed whatever workloads caused that scale out event to occur.


Process

The process to remove a host is documented here. Note that it is a sequential process, with one host being removed at a time. Depending on the number of hosts in your cluster, you may need to adjust your storage and fault tolerance policies as well. To start the process, go to your cloud console and select the SDDC you want to remove the hosts from. If there’s only one cluster, you can click on Remove Hosts under Actions. If there are multiple clusters in the SDDC, you’ll need to select the cluster you want to remove the host from.

You’ll then be advised that you need to understand what you’re doing (and acknowledge that), and you may be advised to change your default storage policies as well. More info on those policies is here.

Once you kick off the process, the cluster will be evaluated to ensure that removing hosts will not violate the applicable EDRS policies. VMs will be migrated off the host when it’s put into maintenance mode, and billing will be stopped for that host.

And that’s it. Pretty straightforward.

VMware Cloud on AWS – Check TRIM/UNMAP

This a really quick follow up to one of my TMCHAM articles on TRIM/UNMAP on VMware Cloud on AWS. In short, a customer wanted to know whether TRIM/UNMAP had been enabled on one of their clusters, as they’d requested. The good news is it’s easy enough to find out. On your cluster, go to Configure. Under vSAN, you’ll see Services. Expand the Advanced Options section and you’ll see whether TRIM/UNMAP has been enabled for the cluster or not.

VMware Cloud on AWS – TMCHAM – Part 11 – Storage Policies

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to cover Managed Storage Policy Profiles (MSPPs) on the VMware-managed VMware Cloud on AWS platform.


Background

VMware Cloud on AWS has MSPPs deployed on clusters to ensure that customers have sufficient resilience built into the cluster to withstand disk or node failures. By default, clusters are configured with RAID 1, Failures to Tolerate (FTT):1 for 2 – 5 nodes, and RAID 6, FTT:2 for clusters with 6 or more nodes. Note that single-node clusters have no Service Level Agreement (SLA) attached to them, as you generally only run those on a trial basis, and if the node fails, there’s nowhere for the data to go. You can read more about vSAN Storage Polices and MSPPs here, and there’s a great Tech Zone article here. The point of these policies is that they are designed to ensure your cluster(s) remain in compliance with the SLAs for the platform. You can view the policies in your environment by going to Policies and Profiles in vCenter and selecting VM Storage Policies.


Can I Change Them?

The MSPPs are maintained by VMware, and so it’s not a great idea to change the default policies on your cluster, as the system will change them back at some stage. And why would you want to change the policies on your cluster? Well, you might decide that 4 or 5 nodes could actually run better (from a capacity perspective) using RAID 5, rather than RAID 1. This is a reasonable thing to want to do, and as the SLA talks about FTT numbers, not RAID types, you can change the RAID type and remain in compliance. And the capacity difference can be material in some cases, particularly if you’re struggling to fit your workloads onto a smaller node count.


So How Do I Do It Then?

Clone The Policy

There are a few ways to approach this, but the simplest is by cloning an existing policy. In this example, I’ll clone the vSAN Default Storage Policy. In the VMware Cloud on AWS, there is an MSPP assigned to each cluster with the name “VMC Workload Storage Policy – ClusterName“. Select the policy you want to clone and then click on Clone.

The first step is to give the VM Storage Policy a name. Something cool with your initials should do the trick.

You can edit the policy structure at this point, or just click Next.

Here you can configure your Availability options. You can also do other things, like configure Tags and Advanced Policy Rules.

Once this is configured, the system will check that your vSAN datastore are compatible with your policy.

And then you’re ready to go. Click Finish, make yourself a beverage, bask in the glory of it all.

Apply The Policy

So you have a fresh new policy, now what? You can choose to apply it to your workload datastore, or apply it to specific Virtual Machines. To apply it to your datastore, select the datastore you want to modify, click on General, then click on Edit next to the Default Storage Policy option. The process to apply the policy to VMs is outlined here. Note that if you create a non-compliant policy and apply it to your datastore, you’ll get hassled about it and you should likely consider changing your approach.


Thoughts

The thing about managed platforms is that the service provider is on the hook for architecture decisions that reduce the resilience of the platform. And the provider is trying to keep the platform running within the parameters of the SLA. This is why you’ll come across configuration items in VMware Cloud on AWS that you either can’t change, or have some default options that seem conservative. Many of these decisions have been made with the SLAs and the various use cases in mind for the platform. That said, it doesn’t mean there’s no flexibility here. If you need a little more capacity, particularly in smaller environments, there are still options available that won’t reduce the platform’s resilience, while still providing additional capacity options.

VMware Cloud on AWS – TMCHAM – Part 10 – Cluster Conversion

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to delve into the topic of cluster conversions on the VMware-managed VMware Cloud on AWS platform.


Background

With the end of sale announcement of the I3.metal node type in VMware Cloud on AWS, I’ve had a few customers ask about how the cluster conversion process works. We’ve previously offered the ability to convert nodes from I3.metal to I3en.metal, and we’ve taken that process and made it possible for the I4i.metal node type as well. The process is outlined in some detail here. From a technical perspective, you’ll need to be on SDDC version 1.18v8 or 1.20v2 at a minimum. From a commercial perspective, to use your existing subscriptions, they’ll need to be flexible, or you can choose to add new subscriptions. Your account team can help with that.


Sounds Easy, What’s the Catch?

I’ve had a few customers run through this process now in my part of the world, and more and more folks are converting across to I4i.metal every week. One of the key considerations when planning the conversion, particularly with smaller environments, is sizing and storage policies. When the team converts your cluster, they will do some sizing estimates prior to the activity, and the results of this sizing might be higher than you’d expect. For example, we talk about the I4i.metal being something in the order of 1.6 – 2 times as powerful as the I3.metal node. But this really depends on a variety of factors, including the vSAN RAID policy in use, the types of workloads running on the cluster, and so forth. I’ve seen scenarios where a customer has wanted to convert a 6-node I3.metal cluster to 4 I4i.metal nodes. From a calculated capacity perspective, this should be a no-brainer. But what you’ll find, when working with the conversion team, is that they will likely come back to you saying that 6 nodes will be the target. The reason for this is that they’re assuming your cluster is running RAID 6.

How do you solve this problem? Think about the vSAN policy you want to run moving forward. If you’re happy to drop to RAID 5, for example, you have a way forward. Once the cluster conversion is complete, jump on and change the default policy to RAID 5 / FTT:1. This will cause vSAN to modify the policy for all of the VMs on the cluster. This is a background process, and won’t interfere with normal operations. Once you’ve done that, you can then remove the additional nodes. It’s a little fiddly, and will require some amount of coordination with the conversion team and your account team, but it’s a fairly simple task, and will get you running on new shiny boxes without having to muck about with setting up another cluster (or SDDC) and manually migrating workloads across.

You’ll want to ensure that changing your RAID policy won’t have an impact on your available storage. Every workload is different, but at a high level, you can use the public sizer to work through some of these numbers. A 16-node I3.metal cluster with RAID 6 configured will give you roughly 165.89 TiB of useable capacity (ignoring management workload overheads and vSAN slack space), and a similar storage footprint can be had with a 8 or 9-node cluster of I4i.metal nodes. You’ll also want to be sure your organisation is comfortable with the vSAN policy you’re moving to. If you’re moving from 16 nodes to 8 or 9 nodes, for example, this isn’t really a problem, as you’ll likely be sticking with RAID 6 for clusters that large. But if you’re going from 6 nodes to 3 nodes, you’re going from RAID 6 to RAID 1.


Thoughts and Further Reading

The neat thing about the VMware Cloud on AWS offering is that it’s a managed service from VMware, and we do a good job of managing boring stuff like this for you, reducing the impact of software and hardware changes by leveraging core VMware technologies that aren’t otherwise available on native cloud platforms. If you’d like to read more about the I4i.metal node – check out our FAQ here.

VMware Cloud on AWS – TMCHAM – Part 9 – Elastic DRS Policy Changes

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to delve into some questions around recent(ish) changes to Elastic DRS policies and capacity on the VMware-managed VMware Cloud on AWS platform.

I’ve had a few customers ask about changes VMware has made to Elastic DRS policies on VMware Cloud on AWS. I’ve talked a little about eDRS previously, and the release notes cover the changes here (go to March 27th, 2023). In short the changes are as follows:

  • Elastic DRS optimize for rapid scaling policy now supports rapid scaling-in to enable faster scaling use cases like  VDI, disaster recovery or any other business needs.
  • The Elastic DRS Cost Policy improvement will allow automated scale-in of a cluster if the storage utilization falls below 40% instead of the current 20% limit.

What does it mean from a practical perspective? Not a lot for customers using the default baseline policy. But if you’re using “Optimize for Lower Cost” or “Rapid Scaling”, it might be worth looking into.


Huh?

Optimize for Lowest Cost

The documentation does a great job of describing how this works: “When scaling in, this policy removes hosts quickly to maintain baseline performance while keeping host counts to a practical minimum. It removes hosts only if it anticipates that storage utilization would not result in a scale out in the near term after host removal”. It has the following thresholds:

Old High Old Low New High New Low
CPU 90% 60% 90% 60%
Memory 80% 60% 80% 60%
Storage 70% 20% 80% (this changed a while ago) 40%

You’ll see that the new low has 40% as the threshold for storage now (I added in the change from 70 – 80% as well, but this was done a while ago). Generally speaking, the algorithm is designed not to do silly things, but we’ve added in this number to enable customers to scale in workloads sooner, helping to reduce the cost of scaling events.

Rapid Scaling

From the documentation: “[t]his policy adds multiple hosts at a time when needed for memory or CPU, and adds hosts incrementally when needed for storage. By default, hosts are added four at a time. You can specify a larger scale-out increment (8 or 12) if you need faster scaling for disaster recovery, Virtual Desktop Infrastructure (VDI), and similar use cases. As with any EDRS policy, scale-out time increases with increment size. When the increment is large (12 hosts), it can take up to 40 minutes to complete in some configurations.

When scaling in, this policy removes hosts rapidly, maintaining baseline performance while keeping host count to a practical minimum. It does not remove hosts if it anticipates that doing so would degrade performance and force a near-term scale-out. Scale-in stops when the cluster reaches the minimum host count or the number of hosts in the scale-out increment has been removed”. This policy has the following thresholds:

Old High Old Low New High New Low
CPU 80% 0% 80% 50%
Memory 80% 0% 80% 50%
Storage 70% 0% 80% 40%

What does that mean? We’ve added in some guardrails for rapid scale-in to ensure that things don’t get too hectic too quickly. And on the flip side, it means that you’ll scale out your environment faster as well. Again, this is useful for bursty workloads such as VDI or, potentially, rapid DR.


Thoughts

Elastic DRS is one of the cooler features of VMware Cloud on AWS. You can do some really interesting things from a scaling perspective, particularly if you’re operating with some volatile / bursty workloads. That said, if you only use the default baseline policy you’ll also likely be in a good spot, as the thing that can really hurt in these kinds of environments is when your hosts run short of storage.

VMware Cloud on AWS – TMCHAM – Part 8 – TRIM/UNMAP

In this edition of Things My Customers Have Asked Me (TMCHAM), I’m going to delve into some questions around TRIM/UNMAP and capacity reclamation on the VMware-managed VMware Cloud on AWS platform.


Why TRIM/UNMAP?

TRIM/UNMAP, in short, is the capability for operating systems to reclaim no longer used space on thin-provisioned filesystems. Why is this important? Imagine you have a thin-provisioned volume that has 100GB of capacity allocated to it. It consumes maybe 1GB when it’s first deployed. You then add 50GB of data to it. You then delete 50GB of data from the volume. You’ll still see 51GB of capacity being consumed on the filesystem. This is because older operating systems just mark the blocks as deleted, but don’t zero them out. Modern operating systems do support TRIM/UNMAP though, but the hypervisor needs to understand the commands being sent to it. You can read more on that here.

How I Do This For VMware Cloud on AWS?

You can contact your account team, and we raise a ticket to get the feature enabled. We had some minor issues recently that meant we weren’t enabling the feature, but if you’re running M16v12 or M18v5 (or above) on your SDDCs, you should be good to go. Note that this feature is enabled on a per-cluster basis, and you need to reboot the VMs in the cluster for it to take effect.

What About Migrating With HCX?

Do the VMs come across thin? Do you need to reclaim space first? If you’re using HCX to go from thick to thin, you should be fine. If you’re migrating thin to thin, it’s worth checking whether you’ve got any space reclamation in place on your source side. I’ve had customers report back that some environments have migrated across with higher than expected storage usage due to a lack of space reclamation happening on the source storage environment. You can use something like Live Optics to report on your capacity consumed vs allocated, and how much capacity can be reclaimed.

Why Isn’t This Enabled By Default?

I don’t know for sure, but I imagine it has something to do with the fact that TRIM/UNMAP has the potential to have a performance impact from a latency perspective, depending on the workloads running in the environment, and the amount of capacity being reclaimed at any given time. We recommend that you “schedule large space reclamation jobs during off-peak hours to reduce any potential impact”. Given that VMware Cloud on AWS is a fully-managed service, I imagine we want to control as many of the performance variables as possible to ensure our customers enjoy a reliable and stable platform. That said, TRIM/UNMAP is a really useful feature, and you should look at getting it enabled if you’re concerned about the potential for wasted capacity in your SDDC.